
- Monthly visits
- 250,617
- 2026-09
- Monthly growth +24.1%
Featherless - Run open models through one inference API
Featherless provides hosted inference for open models through an OpenAI-compatible API. Choose from a catalog of more than 40,000 models, create an API key, and send requests without provisioning GPUs. Chat, Developer, and Business plans differ in intended use, context, concurrency, and billing.
- LLM Developer Tools
- LLM APIs
- GPU Cloud
- open model inference API
- serverless LLM hosting
- OpenAI-compatible model API
Capabilities
Serverless model inference
Run open models through a hosted inference API that returns model responses. Select a model and call it with an API key; Featherless operates the GPU infrastructure, so customers do not provision GPUs or deploy model weights.
Open model catalog
Browse and select from a catalog of more than 40,000 open models. The catalog includes model families, fine-tunes, and community variants, and changing models can be done by changing the model ID in an API request.
OpenAI-compatible API
Send model requests through an OpenAI-compatible API endpoint and receive inference responses. Configure the endpoint and API key in an OpenAI SDK; the Developer and Business plans support production API use.
Dedicated GPU inference
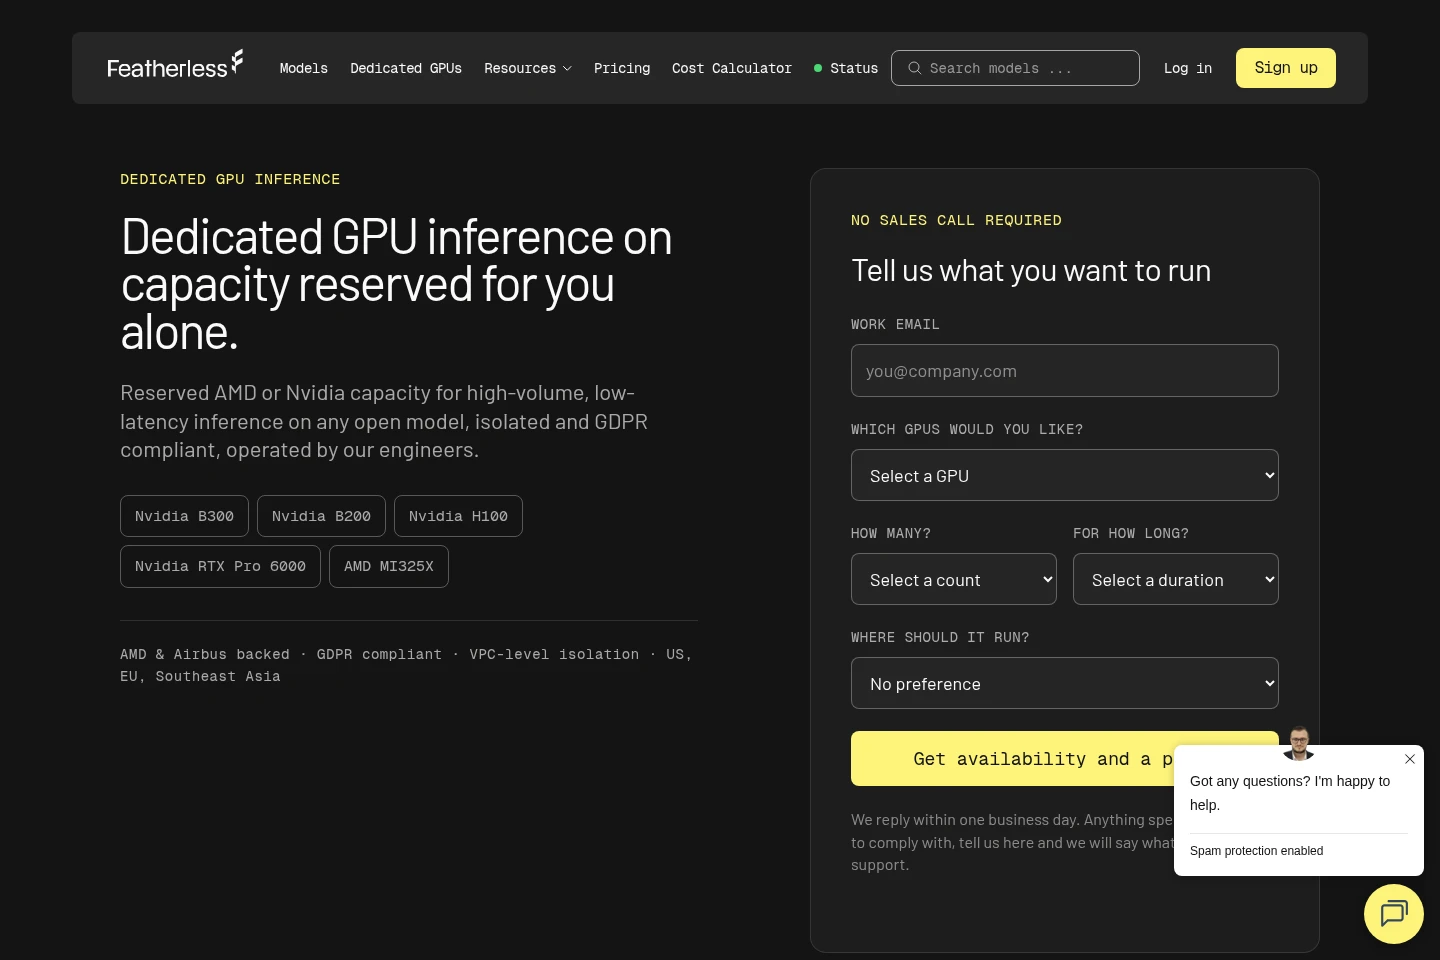
Run inference on reserved GPU capacity with a dedicated endpoint. Choose available Nvidia or AMD accelerators; Featherless engineers manage tuning, and the offering includes VPC-level isolation and GDPR compliance.
Pricing
Featherless offers a monthly Chat subscription, a monthly-credit Developer plan billed per token, and custom Business contracts. Compare intended use, context window, concurrency, and whether billing is flat-rate, token-based, or contracted.
| Plan | Price | Included features and limits |
|---|---|---|
| Chat | $25/month; billed monthly |
|
| Developer | $50 of credits per month |
|
| Business | Custom; annual contracts |
|
Chat subscriptions renew monthly and can be canceled anytime. Developer credits can be topped up with one-time payments; calls pause when the balance reaches zero. Business contract commitment is custom.
Use cases
Integrate an open model into an application
When an application needs hosted LLM inference, select a model, create an API key, and configure the OpenAI-compatible endpoint in an SDK. Requests use the selected model without requiring the application operator to provision GPUs or host model weights.
Connect models to coding agents
When coding agents need model access, use the Developer plan API with supported tools such as Cline, Pi Agent, Kilo Code, OpenCode, OpenHands, and n8n. Requests draw from monthly credits and are billed per token for successful calls.
Run interactive model conversations
When a purchaser wants human-typed chat or roleplay, use the Chat plan with a compatible frontend such as SillyTavern, RisuAI, or Wyvern. It provides unlimited tokens, 32K context, and four concurrent units, subject to its human-driven-use restriction.
Reserve dedicated inference capacity
When a workload needs reserved GPU capacity, specify the models or accelerators, quantity, duration, and region. Featherless sizes a dedicated configuration and operates it for inference; GPU availability and configuration depend on the requested workload.
Limitations
The Chat plan is limited to interactive, human-driven use by the purchaser; app or API traffic, reselling, background automation, and benchmarking are excluded.
Chat provides a 32K context window and four concurrent units; higher context and 100 concurrent units are listed for Developer.
Developer API requests stop when the credit balance runs out, and calls resume only after credits are added.
Business pricing is custom, with annual contracts and volume pricing; capacity and concurrency are sized to the selected GPUs.
Who it is for
Application developers who need hosted open-model inference through an API
Developers running coding agents or production applications that send API traffic
People seeking human-driven model chat through compatible frontend clients
Teams needing reserved GPU capacity, private fine-tunes, or a fixed-cost contract
FAQ
Does Featherless require customers to host GPUs?
No. The serverless inference API runs models on Featherless-managed infrastructure, so customers select a model and use an API key instead of provisioning GPUs or loading model weights.
How are Developer API requests charged?
Successful requests are charged per token at the selected model's input and output rates. Failed requests cost nothing, unused credits do not expire, and calls pause when the balance is exhausted.
Can Chat be used for application or API traffic?
No. Chat is for interactive, human-driven use by the purchaser. App or API traffic, reselling, background automation, and benchmarking are excluded.
What happens when a model is temporarily at capacity?
A saturated model can return HTTP 503, and the failed attempt is not billed. Retry the request or switch to another model; the pricing FAQ suggests contacting support if the issue persists.
Can Chat users switch to Developer for more context?
Yes. Switching from Chat to Developer takes effect immediately, but does not credit or refund the remaining time already paid on Chat. Switching at renewal avoids losing that prepaid period.
What does the Business plan include?
Business is a custom contract for teams seeking guaranteed latency and fixed cost. It lists dedicated GPUs, no shared rate limits, private fine-tunes, named engineers, and an SLA; contracts are annual with volume pricing.
Comments