DeepInfer
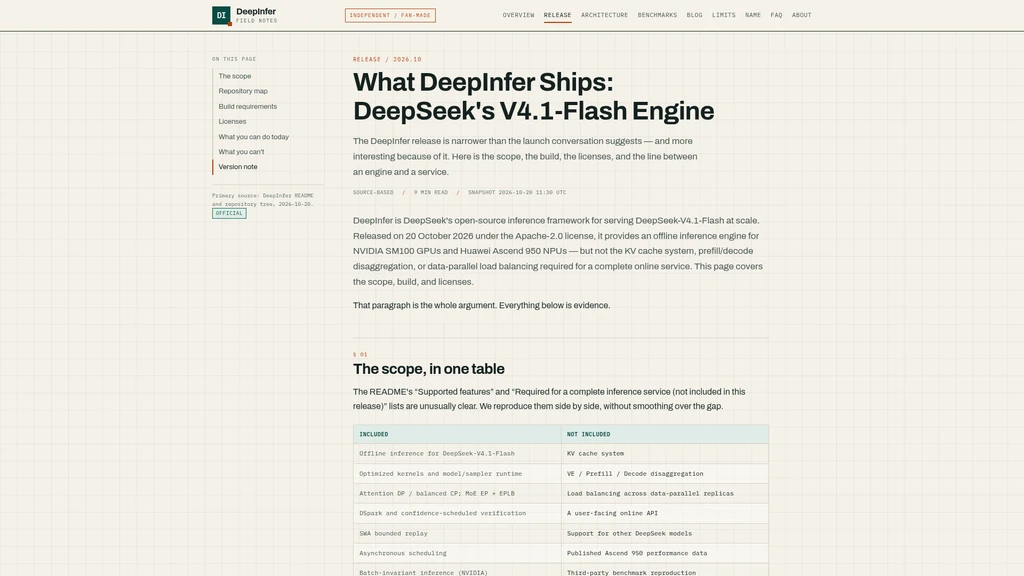
DeepInfer is DeepSeek's open-source Apache-2.0 licensed offline inference framework built to serve DeepSeek-V4.1-Flash at scale. It supports NVIDIA SM100 and Huawei Ascend 950 hardware running on Linux, and is documented via an independent, fan-made reference site that covers release details, architecture, benchmark caveats, and unincluded components. The tool is not a hosted API, user-facing online service, or complete end-to-end serving stack.
Core Capabilities
DeepInfer ships with a pre-integrated stack of optimized components purpose-built for DeepSeek-V4.1-Flash:
A full custom kernel set including FlashMLA, DeepGEMM, DeepEP, TileKernels, DeepSelect, and custom TileLang kernels, assembled from previously released DeepSeek kernel components into a single unified engine.
Parallelism configuration that combines expert parallelism (EP) for MoE layers, attention data parallelism (DP), and balanced context parallelism (CP), designed to spread experts across 64–128 GPUs in production deployments with redundant copies to rebalance hot experts.
DSpark speculative decoding with variable verification, which uses a confidence head to identify which draft tokens require full model validation, delivering a reported 4–7% throughput gain at standard production operating points.
Sliding-window attention (SWA) bounded replay, which limits recompute cost by only replaying the recent tail of the cache rather than rebuilding the full sliding-window cache across every layer, for predictable bounded compute overhead.
Asynchronous scheduling that runs CPU batch preparation work in parallel with active GPU execution, eliminating idle gaps between consecutive decode steps.
Batch-invariant inference and deterministic sampling modes available exclusively on NVIDIA hardware, for auditable benchmarking and consistent agent run behavior.
Native structured output support for regex rules, JSON Schema definitions, and EBNF grammar constraints.
The companion deepseek-recipe library, a separate MIT-licensed repository that provides API protocol conversion and tokenization utilities.
Full offline inference execution for the DeepSeek-V4.1-Flash model.
Intended Audiences
DeepInfer is built for three primary user groups:
Developers working directly with the DeepSeek-V4.1-Flash model who need low-level control over inference execution.
Inference engine researchers studying production-grade LLM optimization patterns, including wide expert parallelism, confidence-guided speculative decoding, and bounded cache replay.
Engineers building custom LLM serving infrastructure who want to adapt DeepSeek's production-derived inference optimizations for their own deployments.
Supported Workflows
The framework is designed for offline inference workloads focused on DeepSeek-V4.1-Flash, with no pre-built user-facing serving layer. Typical usage patterns include:
Integrating the pre-optimized kernel stack and parallelism configuration into custom internal inference pipelines for DeepSeek-V4.1-Flash.
Testing and auditing deterministic inference behavior for benchmarking or agent workloads on NVIDIA hardware.
Implementing structured output constraints for DeepSeek-V4.1-Flash workloads without additional third-party middleware.
Extending the base engine to build custom serving components for specific internal infrastructure requirements.
Researching and modifying state-of-the-art LLM inference optimizations including speculative decoding and MoE load balancing.
Limitations and Explicitly Unincluded Features
DeepInfer has a narrow, defined scope, and does not ship with components required for a full production online serving stack:
It does not include a persistent KV cache system that can survive across separate requests or multiple machines.
It does not implement prefill/decode disaggregation to split workloads across separate dedicated hardware pools.
It does not include data-parallel load balancing across multiple inference replicas.
It is not a user-facing online API, and does not ship with an OpenAI-compatible server, authentication, quota management, billing, or observability tooling.
It is not a general-purpose inference engine, and only supports the DeepSeek-V4.1-Flash model, with no official support for other DeepSeek models or third-party LLMs.
No published performance data is available for Huawei Ascend 950 hardware at the time of release.
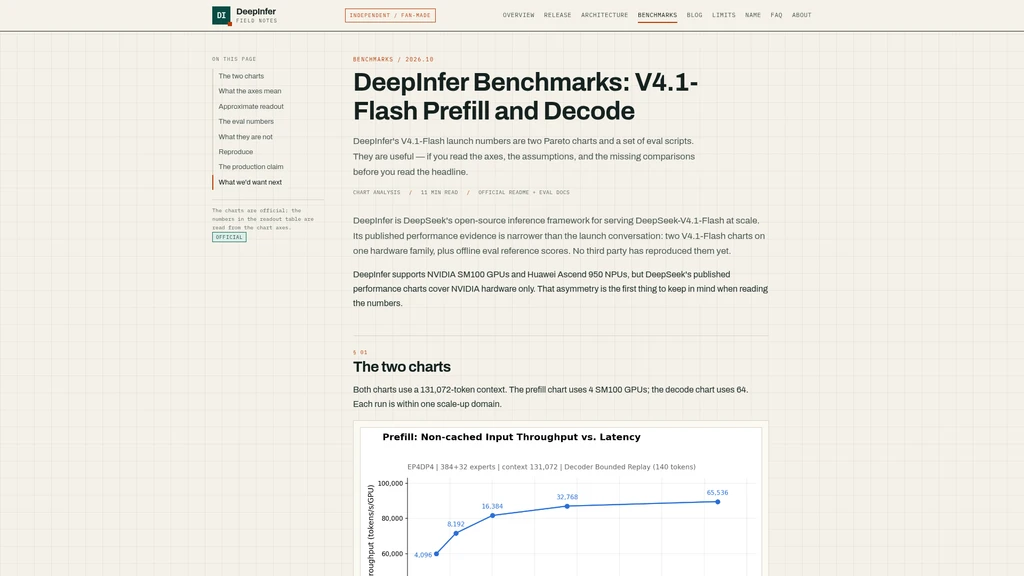
No third-party independent reproductions of the official benchmark charts have been published as of the 2026-10-20 release snapshot.
All official benchmark data is measured at a 131,072 token context length, not the full 1M-token maximum context supported by the DeepSeek-V4.1-Flash model, and the published decode performance numbers assume a 75% draft token acceptance rate that will vary based on input text complexity.
The framework does not support any hardware outside of NVIDIA SM100 and Huawei Ascend 950 on Linux, with no official support for other NVIDIA generations or Ascend chips.
Licensing and Access
DeepInfer is released under the permissive Apache-2.0 license, and is available for free download, modification, and self-hosting with no associated direct pricing. The companion deepseek-recipe library is released under the MIT license. The independent fan-made reference site covering the project is not affiliated with DeepSeek, NVIDIA, or Huawei, and all product claims on the reference site are attributed directly to public official sources.




Comments