
- Monthly visits
- 293
- 2026-09
- Monthly growth -41.6%
Pier - Route AI model requests through one API
Pier provides a single API for connecting an application to more than 250 AI models. It supports model fallbacks, load balancing, retries, caching and canary tests, with deployment, usage metrics, logs, user management and cost tracking. The site lists a free Trial plan and an Enterprise plan with contact-based pricing.
- LLM Developer Tools
- LLM APIs
- GPU Cloud
- LLM Observability
- AI model routing
- LLM API management
- AI model observability
Capabilities
Unified model API
Connect applications to more than 250 AI models through one API. Use a single API key to call models and configure fallback models, load balancing, retries, caching and canary tests.
Model deployment and scaling
Deploy multiple models for an application and manage scaling through Pier. The page describes one-click agent deployment and says Pier handles deployment and scaling.
Usage observability
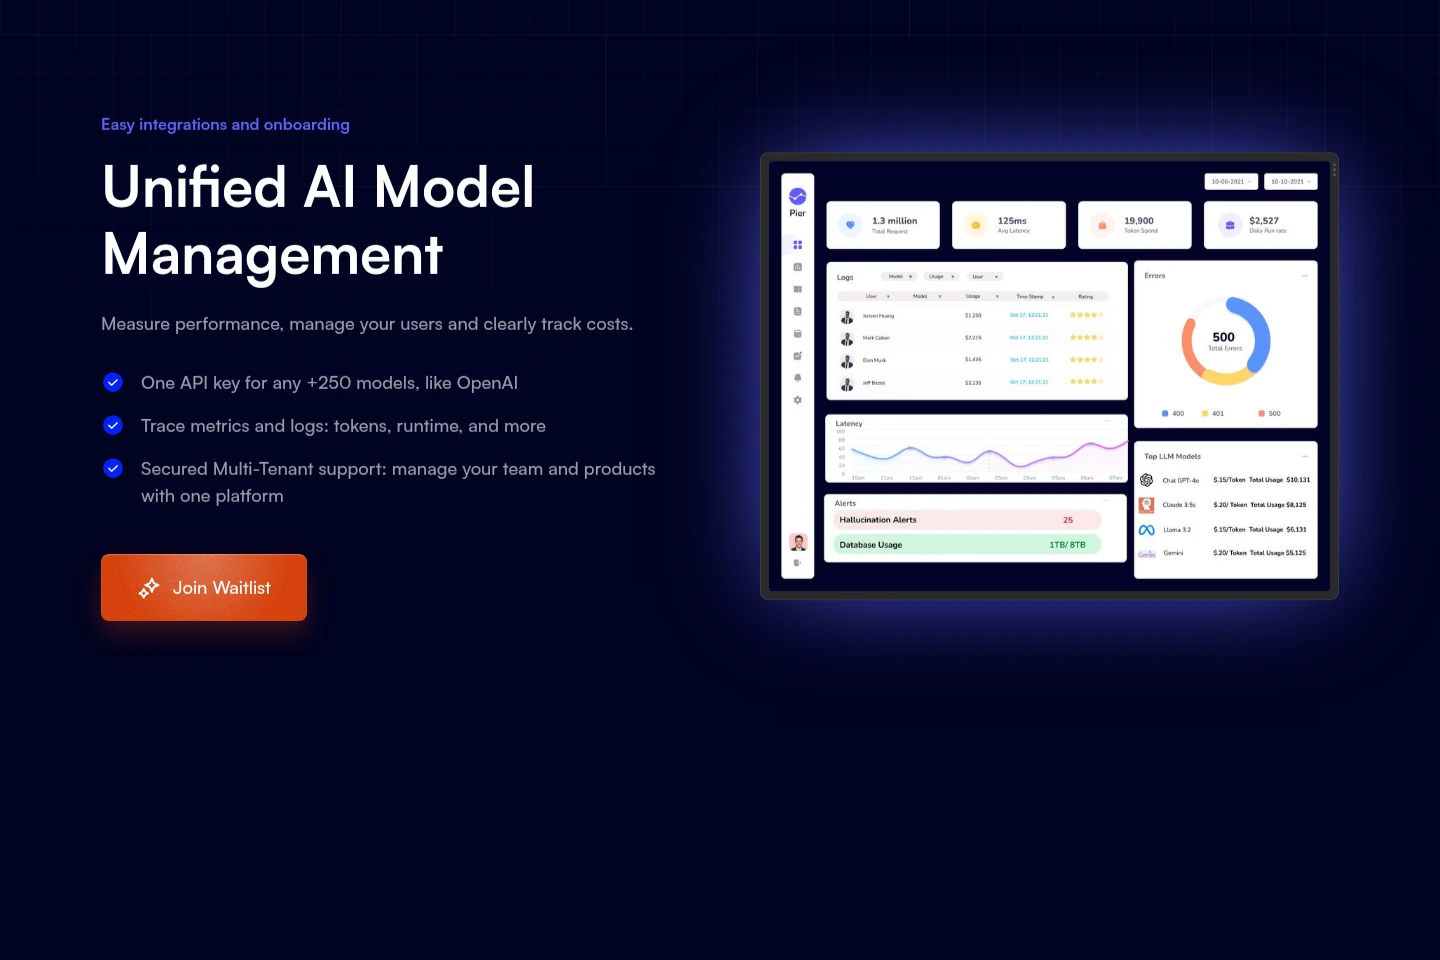
View usage metrics and logs, including tokens and runtime, and manage users and costs. The site describes management of usage and users in one place; the Trial plan includes 30-day logging and metrics.
Multi-tenant management
Manage teams and products on one platform with multi-tenant support. The page describes this support as secured, without specifying further security controls.
Pricing
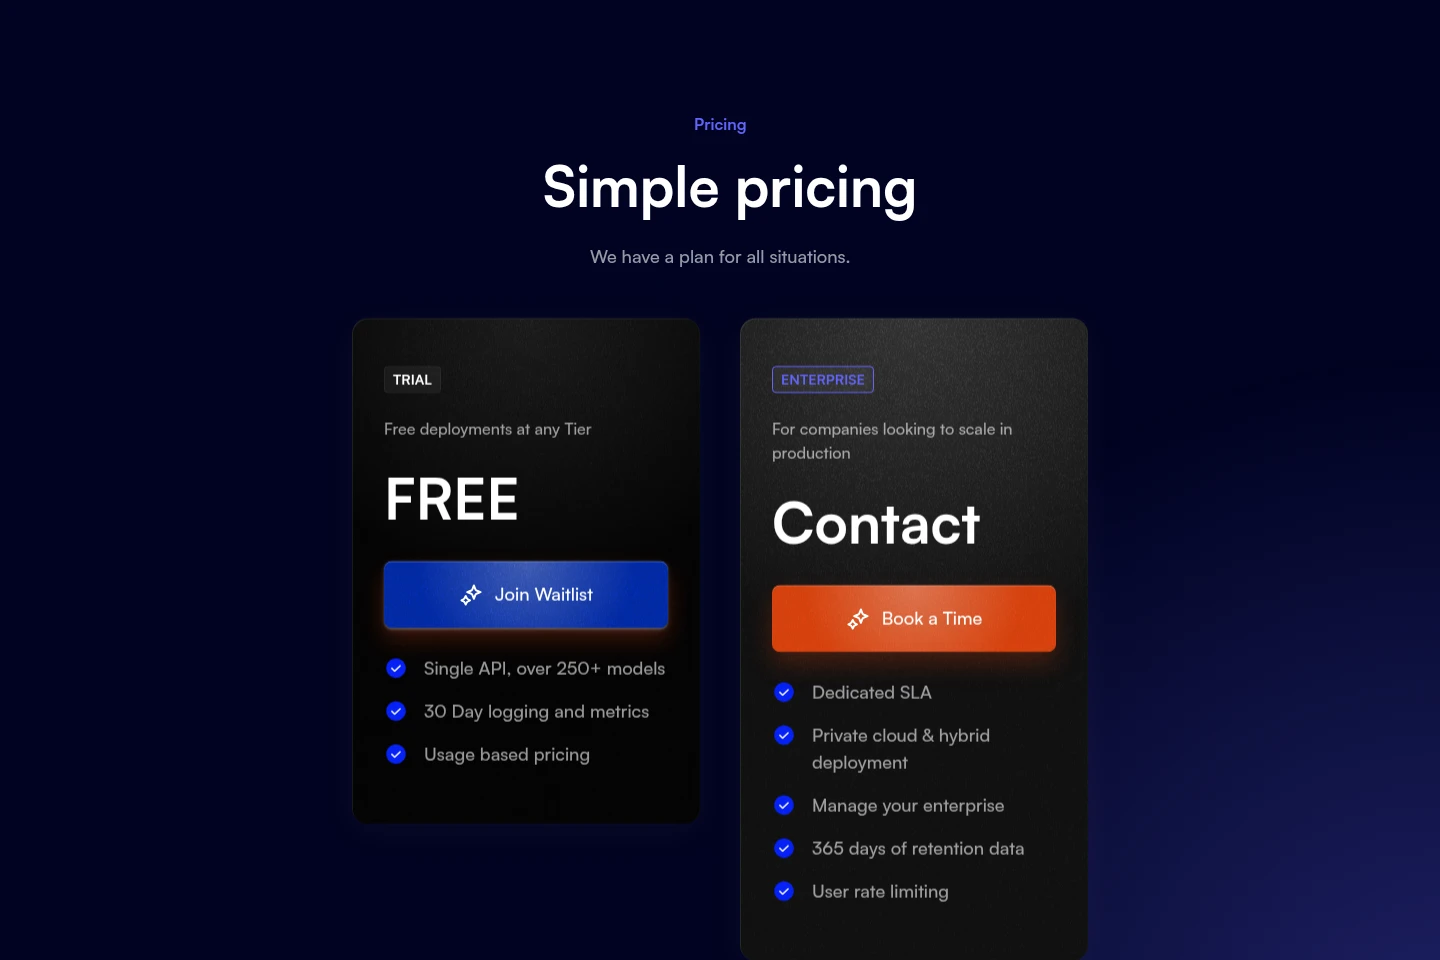
Pier lists a free Trial plan and an Enterprise plan with contact-based pricing. Compare model access, logging retention, deployment options and enterprise controls when choosing.
| Plan | Price | Included features and limits |
|---|---|---|
| Trial | Free |
|
| Enterprise | Contact for pricing |
|
Use cases
Connect an application to AI models
When an application needs to call different AI models, use Pier's single API and API key to access more than 250 models. The integration can use fallbacks, load balancing, retries and caching.
Deploy and scale models for an application
When deploying models or agents for a product, use Pier's deployment and scaling capabilities to manage deployment through the platform. The Enterprise plan also lists private cloud and hybrid deployment.
Review model usage and application costs
When teams need visibility into model activity, review available usage metrics and logs, including tokens and runtime, and track costs. The Trial plan lists 30-day logging and metrics; Enterprise lists 365 days of retention data.
Limitations
The Trial plan specifies 30 days of logging and metrics; longer retention is listed as 365 days for Enterprise.
Enterprise pricing is shown as Contact, with a booking link rather than a published price.
The site directs visitors to join a waitlist to try Pier; it does not describe immediate self-serve signup.
Who it is for
Teams building applications that call multiple AI models
Companies deploying agents and managing multiple products or teams
Organizations seeking model usage monitoring and deployment options for production
FAQ
How does Pier connect to AI models?
Pier provides one API and one API key for more than 250 models. Applications can use model fallbacks, load balancing, retries, caching and canary tests.
What usage information can teams review?
The platform describes metrics and logs such as tokens and runtime, along with user and cost management. The Trial plan lists 30-day logging and metrics.
What is included in the Trial plan?
The Trial plan lists free deployments at any tier, a single API for over 250 models, 30-day logging and metrics, and usage-based pricing.
How is Enterprise priced?
Enterprise pricing is listed as Contact. The page provides a booking link and lists a dedicated SLA, private cloud and hybrid deployment, 365 days of retention data, and user rate limiting.
Comments