Mistral Large 4
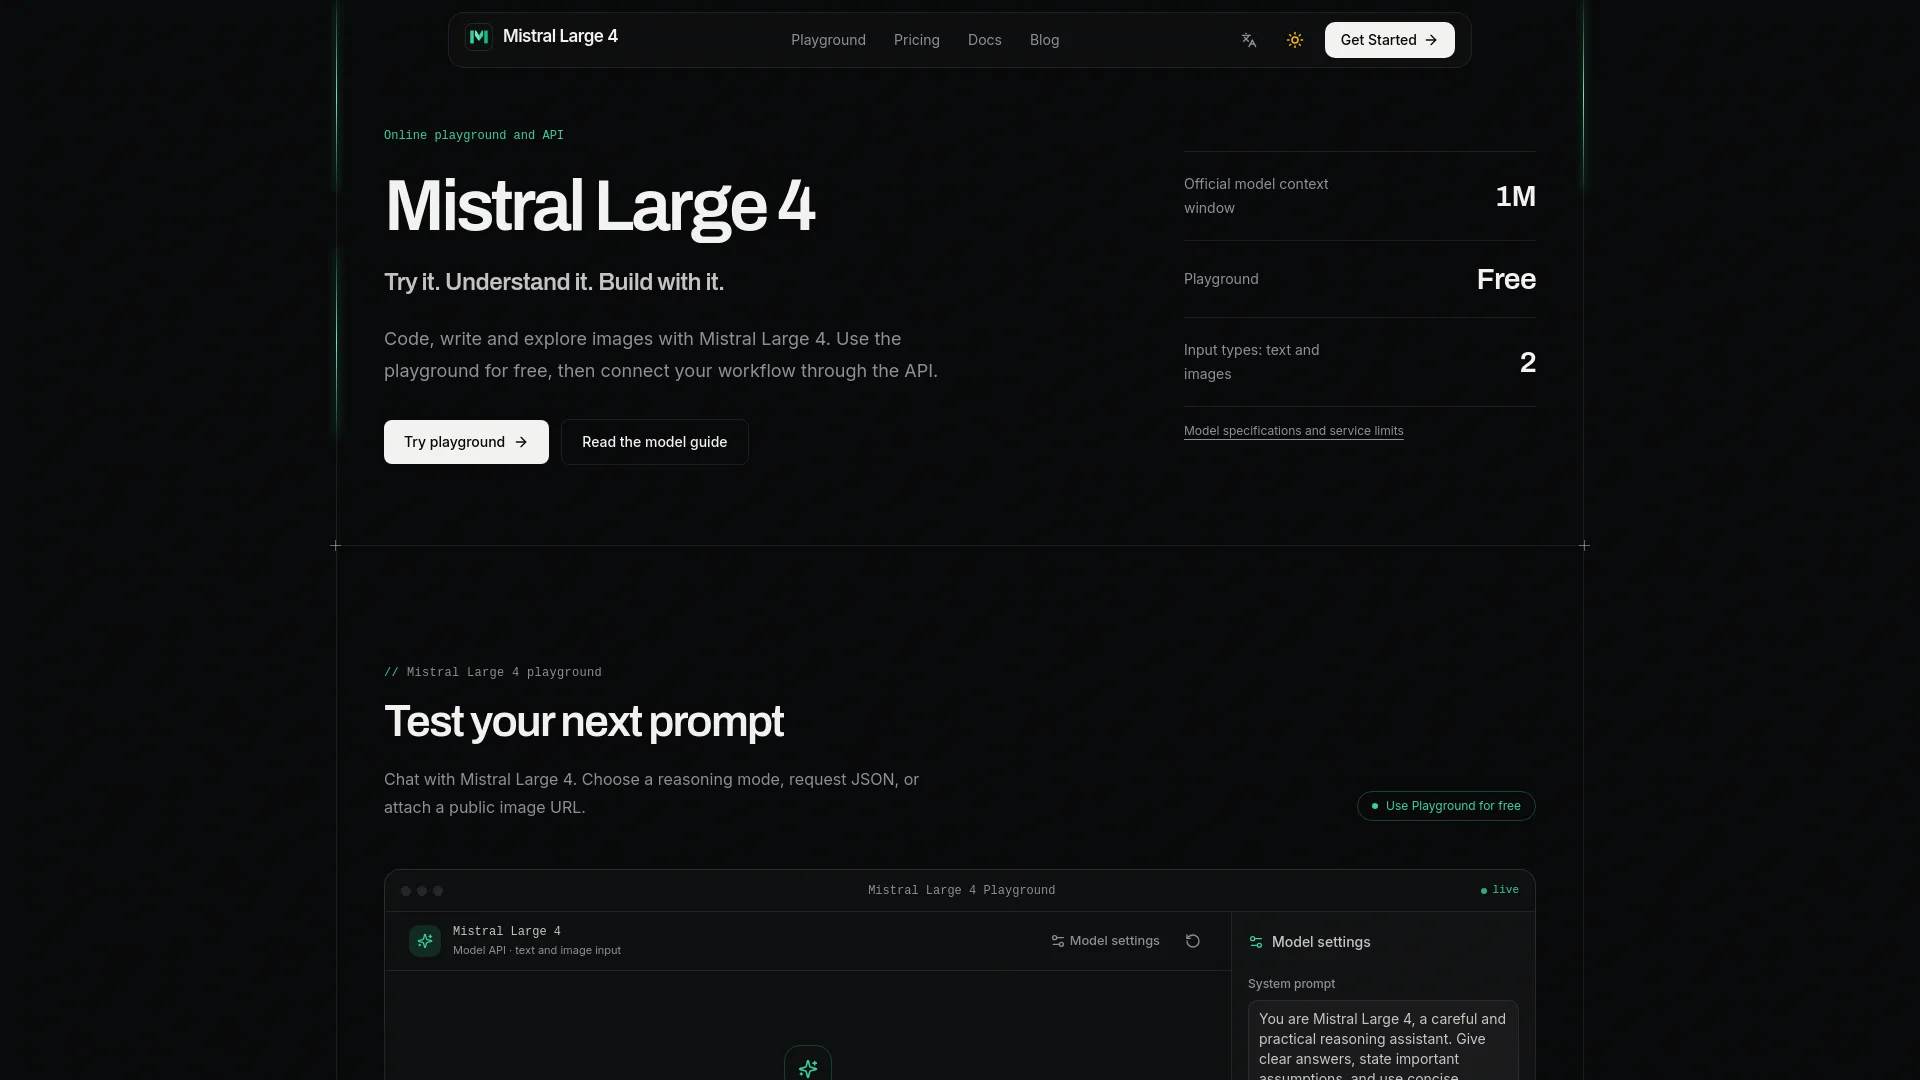
Mistral Large 4 is a general-purpose multimodal AI model available via a free browser-based playground and an OpenAI-compatible REST API, built to support common AI tasks including coding, document analysis, image interpretation, writing, and structured data generation. The model features an official 1M-token context window, with adjustable controls to fine-tune output behavior for different use cases.
Core Capabilities
Mistral Large 4 supports both text and image input to handle a wide range of practical tasks out of the box. Users can submit code snippets for review, paste document excerpts to ask targeted questions, or share public image URLs to interpret screenshots, diagrams, and visual data.
For API-based workflows, the model supports custom function calls to enable tool integrations such as external search or internal data lookup, with full control over execution logic kept on the user’s side. The model can generate structured JSON output natively for use cases including content classification, data extraction, and workflow planning, eliminating the need for additional parsing steps for downstream systems that expect predictable formatted data.
Built-in configurable controls let users adjust behavior per request: users can set custom system prompts to define the assistant’s default role and output style, adjust temperature to control output randomness, and toggle reasoning effort between direct, low-effort responses and deeper, high-effort reasoning for complex problem solving.
The free online playground requires no coding to test prompts, while the API includes native streaming support for real-time response delivery in integrated applications.
Supported Workflows
The no-code playground workflow is designed for fast, low-friction testing:
Sign in to access the free playground interface
Paste text or code directly into the input field, or add a public image URL alongside your prompt, and adjust model settings including reasoning effort, temperature, and maximum output tokens as needed
Review the model’s response, refine your query with follow-up prompts, and validate outputs against your source material before scaling to larger integrations. For PDF content, extract relevant text excerpts first to submit via the text input.
For developer API integrations, the workflow uses standard OpenAI-compatible tooling:
Generate a server-side API key in your account settings, and configure your OpenAI client to point to the Mistral Large 4 API base URL
Send requests with your text, image URLs, custom system prompts, and any defined tool functions, specifying your desired reasoning effort level and output format
Validate any returned tool call requests in your own application logic before executing approved functions, and pass results back to the model to continue the workflow. You can enable streaming to deliver incremental responses to end users as they are generated.
Intended Audiences
Mistral Large 4 is built for four primary user groups:
Developers building custom AI applications and agents who need a flexible, OpenAI-compatible endpoint to integrate multimodal, tool-calling capabilities without custom model hosting
Casual users and prompt engineers who need to test, iterate on, and refine AI prompts without writing code or managing infrastructure
Cross-functional teams working on coding review, document analysis, and image interpretation projects who need a shared environment to test outputs before rolling out workflows at scale
Organizations looking to integrate general-purpose multimodal AI capabilities into their existing internal workflows, with configurable usage billing to match variable demand.
Pricing and Usage Terms
Mistral Large 4 operates on a freemium model. The online playground is available for free after sign-in, with all usage beyond the free allowance calculated using a credit system: credits are computed as actual model cost in USD multiplied by 12,000, rounded up to the nearest whole number. All requests that are admitted for generation count toward usage, even if they are later cancelled or fail to complete.
One-time credit packs are available for users with occasional or project-based usage: these packs never expire and do not auto-renew. Available one-time packs include 80,000 credits for $10, 1,000,000 credits for $100, and 11,000,000 credits for $1000.
Monthly subscription plans grant a set number of credits each billing period, with each credit grant valid for 90 days from the date it is added to the account. All plans include access to the full playground feature set, adjustable model controls, API access, and email support.
Current Limitations
As of October 7, 2026, the following service limitations apply:
The free playground does not support PDF uploads, audio input, or video input. It only accepts pasted text and public image URLs.
Playground input limits are set to 24 total messages per conversation, 24,000 characters per individual message, 96 KiB per full request, and a maximum of 16,384 output tokens. The model’s official 1M-token context window is not the active input allowance for the playground interface.
The public API integration is configured around a 524,288 token context limit, which is lower than the model’s stated maximum 1M-token capacity.
Model weights are not yet available for self-hosting, with a public release planned for the end of October 2026. No self-hosted deployment or commercial licensing terms are confirmed ahead of that release.
The hosted playground is not a private deployment. Confidential company documents or sensitive regulated data should not be submitted to the playground, and users are advised to review the platform’s privacy policy for details on data processing, retention, and geographic hosting regions before processing sensitive content via the API.




Comments